Why can’t Claude read Reddit, and how do you fix it?
Claude’s own tools refuse reddit.com before the page loads. Web fetch in Claude Code checks a blocklist and stops. According to the bug reports, Claude in Chrome has refused every Reddit address since 18 September 2026. I built an open source tool that has your own browser open the Reddit page and hand Claude the text.
Claude in Chrome answers every reddit.com, old.reddit.com and redd.it address with “This site is not allowed due to safety restrictions.” The bug report was opened on 18 Sep 2026. On 19 Nov 2026 it was still open, with 29 comments and no reply from Anthropic.
Why I built it
On 14 November 2026 someone on r/ClaudeAI asked how to get around the block. They had a consular application to fill in, the instructions were unfriendly, and the people who had been through it were on Reddit. Claude said it could not go and look. ChatGPT could, and that is how they got it done.
I answered that I had told Claude to build me a browser extension for this, and that it used it every time it needed Reddit. It ended up as the top comment in the thread, and then someone replied in Spanish, asking if I could share it, because they had been fighting this for months.
That reply is why this page exists. Four days later, on 18 November, I published one that anyone can install: read-only-reddit-old, free, under the MIT licence.
Why Claude can’t access Reddit
Claude has two normal ways to reach a web page from your machine. Both stop at Reddit.
The first is web fetch in Claude Code. Before it requests a page, it sends the hostname to Anthropic and checks it against what the docs call a “domain safety blocklist”. On 19 November 2026 the answer for Reddit was no: “Claude Code is unable to fetch from www.reddit.com”. The docs add that Claude Code never contacted the site, because the check runs first. They do not say why a site is on the list.
The second is Claude in Chrome, the extension that lets Claude work in your browser. Its help pages name the kinds of site it stays away from: banks, investment platforms, crypto exchanges, adult content and piracy. Reddit is not among them. But since 18 September 2026 users report the same refusal on every Reddit address, including old.reddit.com and the redd.it short links. Removing reddit.com from the approved sites and adding it back changes nothing.
Anthropic has not explained it. One user in the bug report says a support agent called it a known bug and not a deliberate restriction. That is second-hand. On 19 November the block was two months old.
People in the report point to the dates. A San Francisco judge let most of Reddit’s scraping lawsuit against Anthropic go ahead in an order dated 17 September, the day before the block appeared. Nobody at Anthropic has linked the two. The dates fit, and it is still a guess.
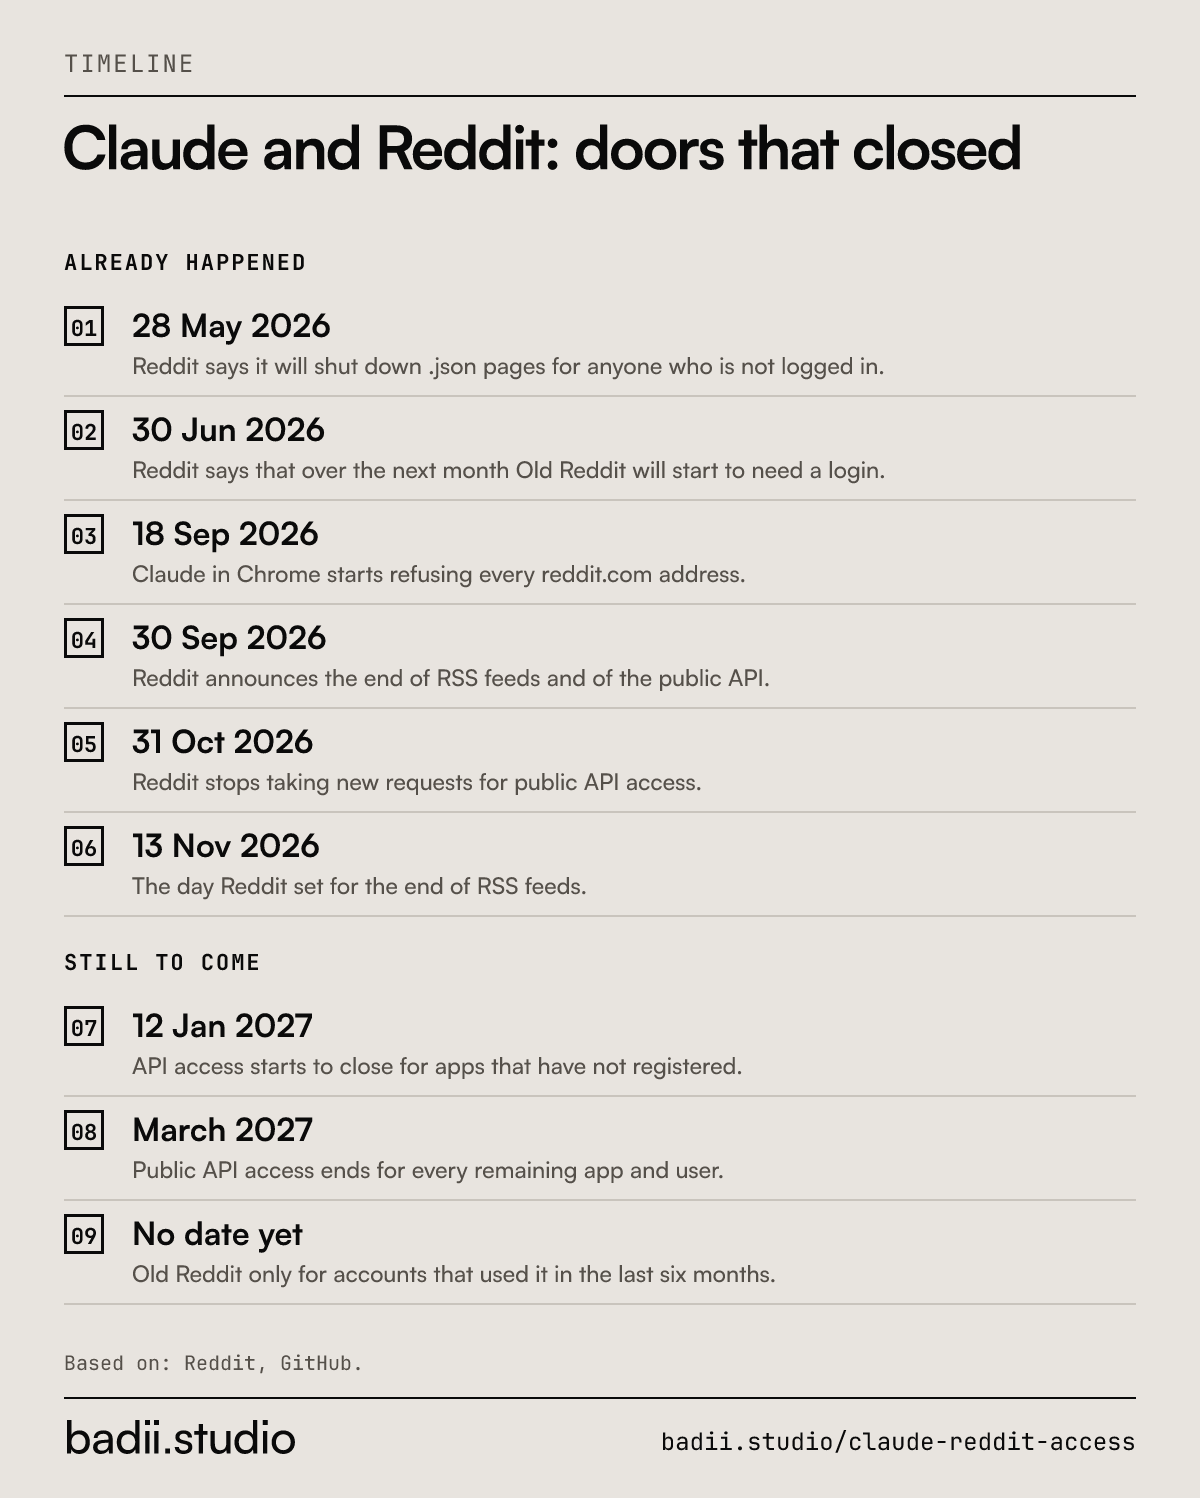
The numbers as text
- 28 May 2026: Reddit says it will shut down .json pages for anyone who is not logged in.
- 30 Jun 2026: Reddit says that over the next month Old Reddit will start to need a login.
- 18 Sep 2026: Claude in Chrome starts refusing every reddit.com address.
- 30 Sep 2026: Reddit announces the end of RSS feeds and of the public API.
- 31 Oct 2026: Reddit stops taking new requests for public API access.
- 13 Nov 2026: The day Reddit set for the end of RSS feeds.
- 12 Jan 2027: API access starts to close for apps that have not registered.
- March 2027: Public API access ends for every remaining app and user.
- No date yet: Old Reddit only for accounts that used it in the last six months.
Cite as: badii.studio, "Claude and Reddit: doors that closed", https://badii.studio/claude-reddit-access#claude-and-reddit-doors-closed-2026
Reddit is shutting things down too
Even without Anthropic’s block, the other ways into Reddit are closing. Reddit’s stated reason is the same each time: scraping and automated abuse.
It is probably also why ChatGPT could help the person in that thread. Google said in February 2024 that it has access to Reddit’s Data API, and OpenAI signed its own deal that May. In October 2026 CNBC still named those two as Reddit’s biggest data-licensing partners. Anthropic is not a partner. Reddit sued it in June 2025.
- Logged-out .json pages: Reddit said on 28 May 2026 that it would shut them down.
- Old Reddit: it has needed a login since mid 2026. Reddit says that in the next few months it will only open for accounts that used it in the last six months, and for moderators.
- RSS feeds: Reddit set 13 November 2026 as the last day. For feeds outside a community you moderate, its post says, “there is no replacement.”
- The public API: no new access requests since 31 October 2026. Access starts to close for unregistered apps on 12 January 2027, and ends for every remaining app and user in March 2027.
The tool: your own browser does the reading
read-only-reddit-old automates the routine I was already doing by hand: open the thread, copy it, paste it into Claude. That is all it does.
It has three small parts. A Claude Code skill tells Claude when to use Reddit and how to keep the page count low. An MCP server gives Claude four tools: status, search, read_thread and read_listing. A browser extension does the reading. Without the tests, the whole thing is 1,257 lines of plain JavaScript with no runtime dependencies, so you can read all of it before you trust it. I would.
When Claude asks for a thread, the request waits in a queue on your machine. The extension picks it up, opens the page on old.reddit.com in one background tab, reads the text off the page and passes it back. It runs in your normal browser profile with your own Reddit login. It needs no API key, no RSS feed and no second account.
It does not go through Claude in Chrome or web fetch at all, so their blocklists do not apply.
Why Old Reddit first and not the new site? Purely to save tokens. Old Reddit serves the post and its comments as one plain page, and the extension sends Claude only the text. The thread that started all this is 3.4 MB when I save it from new Reddit as HTML. Read through the tool, its post and 31 comments reached Claude as 11,140 characters. The new site is only the fallback, as you will see below.
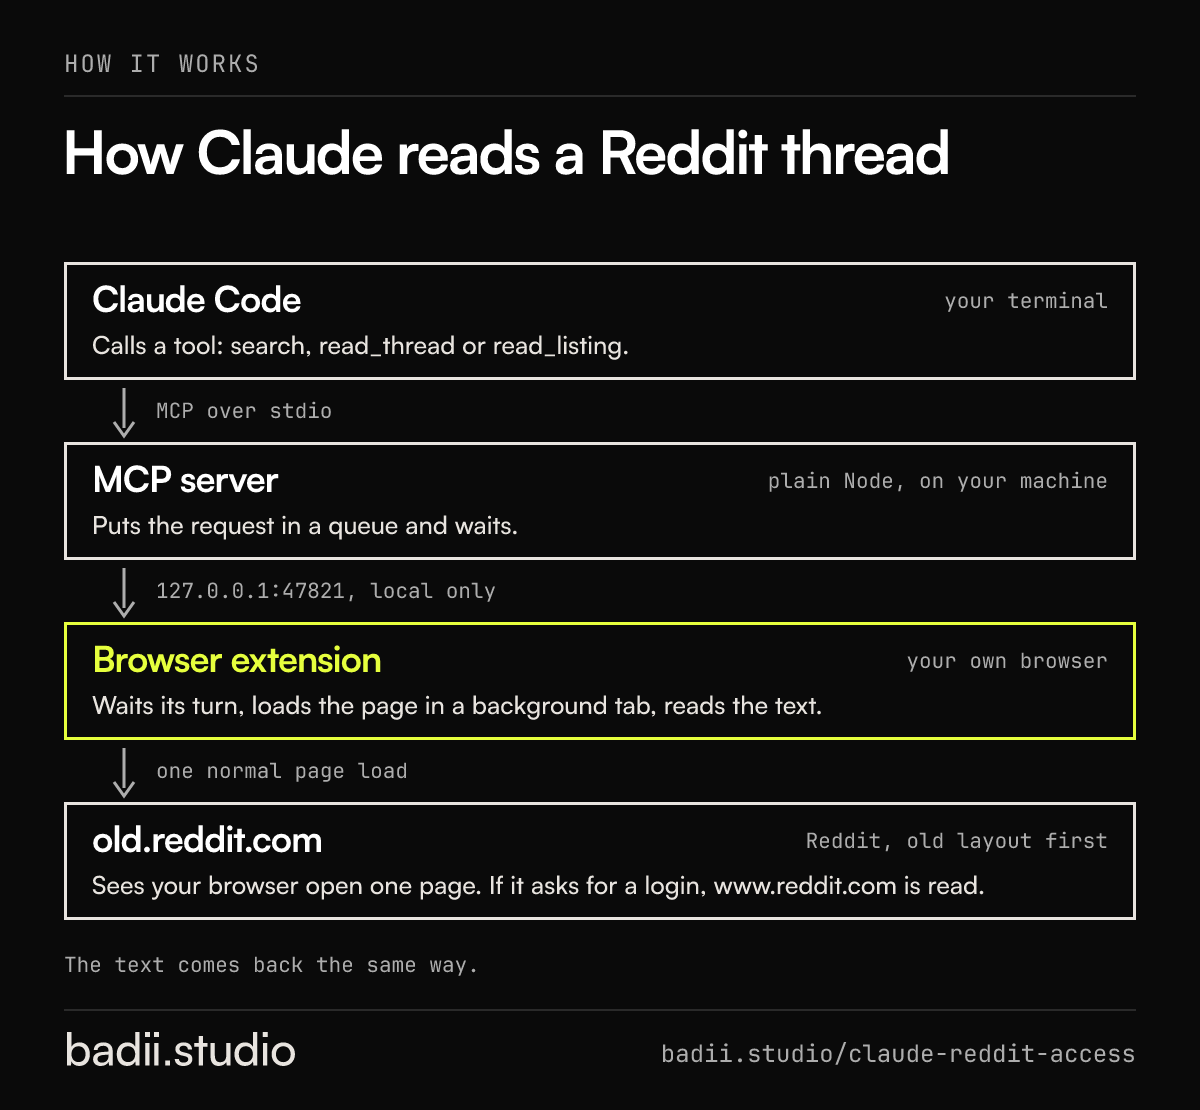
Cite as: badii.studio, "How Claude reads a Reddit thread", https://badii.studio/claude-reddit-access#how-claude-reads-a-reddit-thread
What Claude gets back
A thread comes back as plain text: the post, then the comments as an indented tree, with the author, the score and the date on each one. The original poster is marked (OP). Links keep their targets.
The tree is the part I care about. On Reddit the useful answer is often the reply that corrects the top comment, and you only see that if the nesting and the scores are kept.
Replies that Reddit hides behind “load more comments” are listed as not loaded. The extension never clicks anything, so it tells Claude what it skipped.
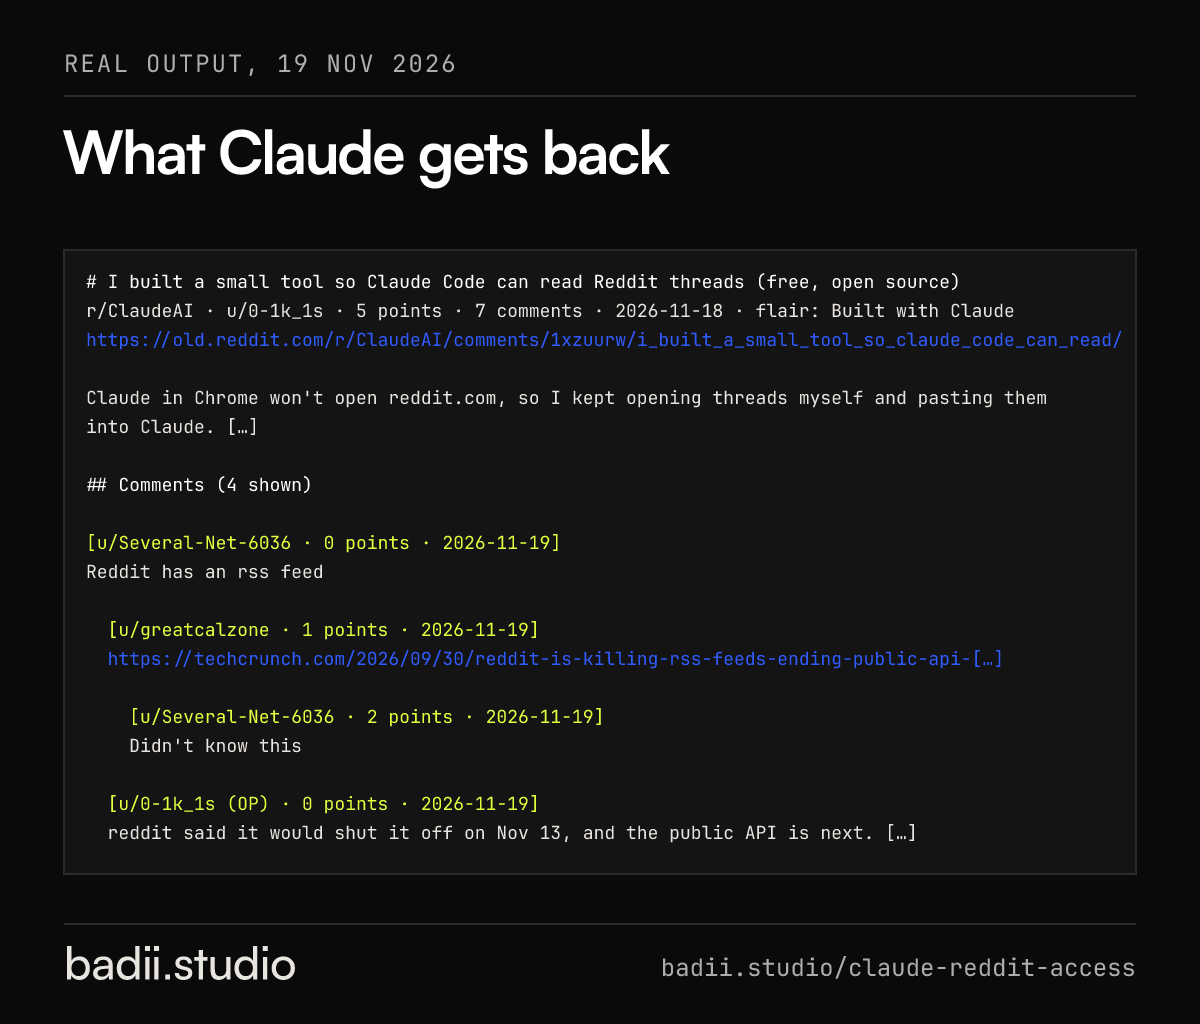
Cite as: badii.studio, "What Claude gets back from a Reddit thread", https://badii.studio/claude-reddit-access#read-only-reddit-old-thread-output
It is slow on purpose
A scraper wants thousands of pages. This tool wants the few pages a person would have opened anyway, at about the speed a person reads them. The skill tells Claude to pick the best three to six threads and leave the rest.
A normal research job, one search and five threads, takes one to two minutes. You will notice the wait. You will not mind it.
For this article I read seven Reddit pages through it on 19 November 2026: one search and six threads, Reddit’s own announcements among them. No call took longer than 17 seconds.
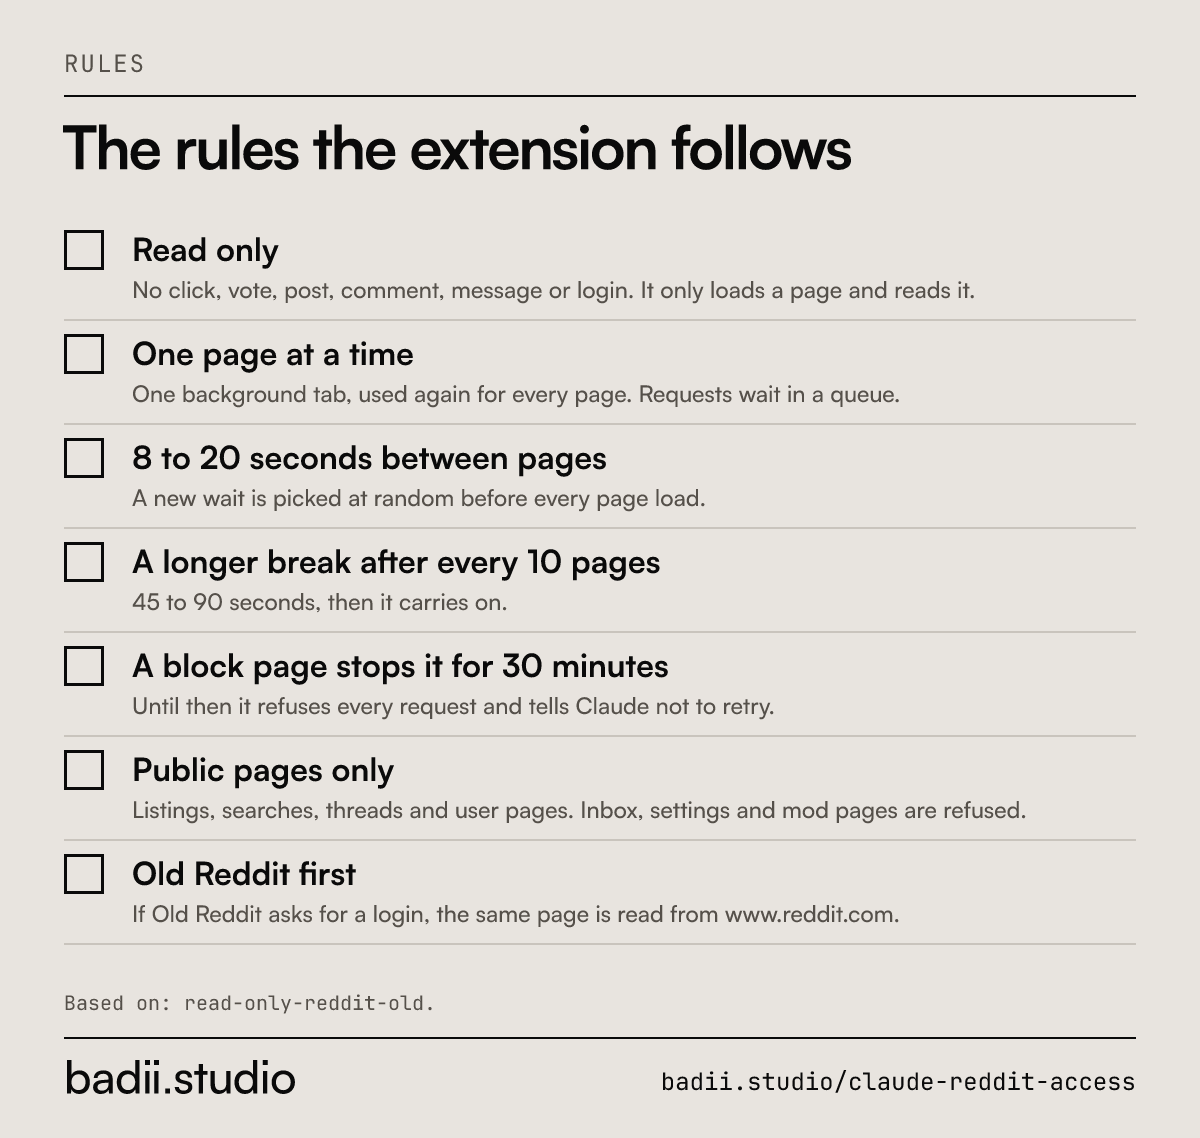
The numbers as text
- Read only: No click, vote, post, comment, message or login. It only loads a page and reads it.
- One page at a time: One background tab, used again for every page. Requests wait in a queue.
- 8 to 20 seconds between pages: A new wait is picked at random before every page load.
- A longer break after every 10 pages: 45 to 90 seconds, then it carries on.
- A block page stops it for 30 minutes: Until then it refuses every request and tells Claude not to retry.
- Public pages only: Listings, searches, threads and user pages. Inbox, settings and mod pages are refused.
- Old Reddit first: If Old Reddit asks for a login, the same page is read from www.reddit.com.
Cite as: badii.studio, "The rules the extension follows", https://badii.studio/claude-reddit-access#read-only-reddit-old-rules
The bug Claude could not see
I described the idea in one Claude Code session and Claude wrote the code. Then it had to be tested. Claude could not open Reddit to check its own selectors. Same block.
So I saved two pages from my browser as HTML files, a search page and one long thread, and Claude ran its code on those.
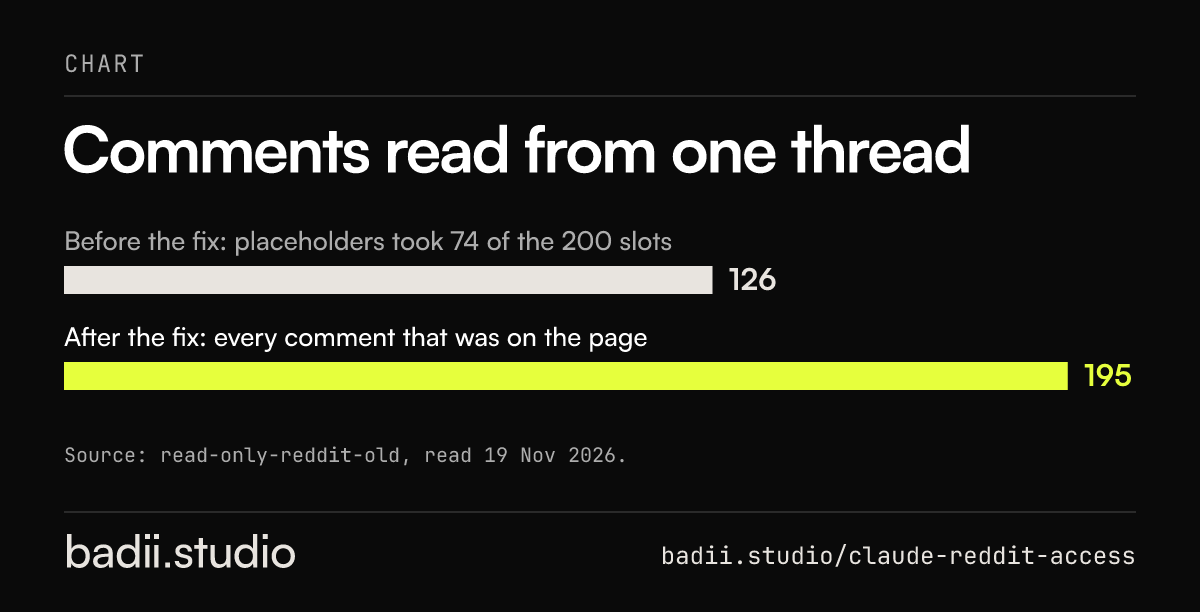
That caught a real bug. The reader stops at 200 comments by default, and it was counting every “load more comments” placeholder as a comment. On the saved thread, 74 of the 200 slots went to placeholders. Claude would have received 126 comments and a note that the thread had been cut. The note would even have been true. After the fix it gets all 195 that were on the page.
The repository now has 69 tests in its normal run, and none of them opens Reddit. What I took from it is nothing new. Code an AI writes is only as good as the way you check it, and “it ran” is not a check.
The numbers as text
- Before the fix: placeholders took 74 of the 200 slots: 126
- After the fix: every comment that was on the page: 195
Cite as: badii.studio, "Comments read from one thread", https://badii.studio/claude-reddit-access#reddit-comments-read-before-and-after-fix
The update I pushed while writing this
Version 1.0.0 read Old Reddit and nothing else. While I was writing this article and reading Reddit’s own announcements, I saw that this was a real blocker. Old Reddit already asks for a login. Soon it will only open for accounts that used it in the last six months. Anyone outside that group would install the tool and get nothing.
So I pushed an update quickly. Version 1.1.0 went out on 19 November 2026, one day after the first release. (Goddamn, I love this era of Claude.)
Now the tool tries Old Reddit first. If Old Reddit asks for a login, it reads the same page from www.reddit.com, and the output starts with a note that says so. Then it skips Old Reddit for an hour. If both layouts ask for a login, Claude gets a clear error and asks you to log in. It never asks for your password.
The fallback is thinner, and I would rather say so than let you find out. The new site loads most of its comments and search results when you scroll or click, and the extension does neither. So a fallback read returns fewer comments, fewer results and no next page. The login wall detection has also not been checked against a real wall yet. Both gaps are open issues.
As for me, this does what I need. Anything else that would improve quality of life is in the issues and their comments.
How to install it
You need Node 22 or newer, a Chromium browser such as Chrome, Brave or Edge, and Claude Code. Being logged in to Reddit in that browser gives the best results, because Old Reddit needs a login. The exact commands are in the README.
- Clone the repository into your Claude Code skills folder as ~/.claude/skills/read-only-reddit-old. The folder name has to be exactly that.
- Open your browser’s extensions page, turn on Developer mode, click “Load unpacked” and pick the extension folder inside the clone.
- Register the MCP server with one command: claude mcp add --scope user read-only-reddit-old -- node, followed by the full path to mcp-server/src/index.js.
- Start a new Claude Code session and ask it to search Reddit for something. The extension can take up to 30 seconds to connect. Give it that long before you decide it is broken.
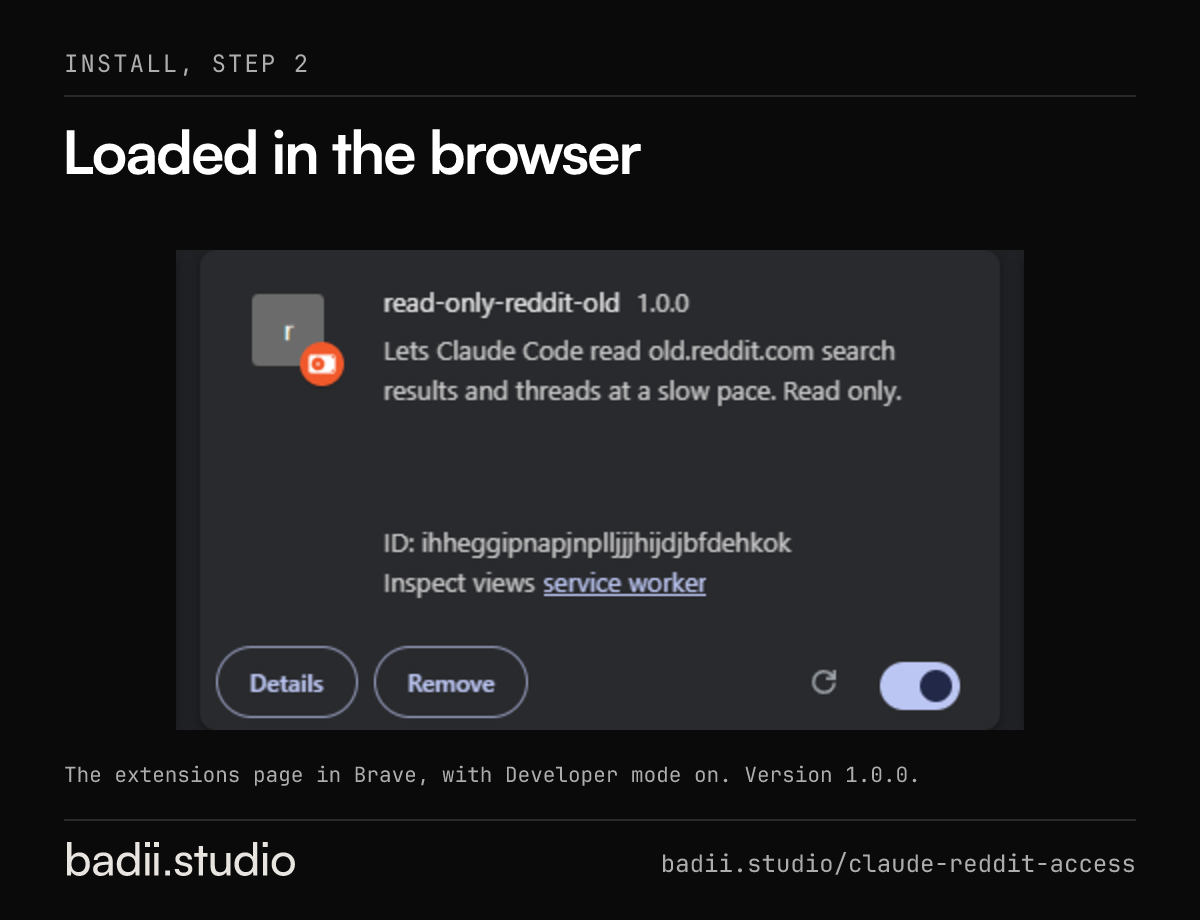
Cite as: badii.studio, "read-only-reddit-old loaded in the browser", https://badii.studio/claude-reddit-access#read-only-reddit-old-extension-loaded
Other ways in, and when they are better
Mine is one option. The thread had others, and some fit a different job better. I checked each of these on 19 November 2026.
- Ask another AI. ChatGPT and Gemini come from the two companies with Reddit data deals. If you need one answer and no comment tree, that is the shortest route. Yes, that means not using my tool.
- An MCP server on the archive. Some read Arctic Shift, a free archive of Reddit that needs no key. Its maintainer said in October that comments arrive one to two days late, so it suits old threads better than this week’s. The maintainer has also said they are not sure yet what the March 2027 shutdown will do to it.
- An MCP server on the official API. The most starred one I found, reddit-mcp-buddy, now needs the credentials of a Reddit app that Reddit has already approved for API access. New requests closed on 31 October 2026.
- A general browser tool. Playwright MCP can drive a browser where you are logged in, and browserd was built for the same job. Tools like these can also click and type, which is more power than reading a thread needs.
- A search API. Brave lists $5 per 1,000 requests, with $5 of free credit a month. You get results and snippets, and none of the ones I looked at promises the full comment tree.
- Copy and paste. It still works, and it is what I did until I got tired of it.
The limits, and the risk you take
- Reddit’s User Agreement, in force since 1 July 2026, forbids collecting data from the site “by any means (automated or otherwise)” outside its terms, and says scraping without Reddit’s written consent is prohibited. This tool loads one page at a time in your own browser, the way you would, but it is still automated. I will not tell you Reddit allows it. The account is yours, so you decide.
- It works best on Old Reddit. Reddit plans to limit Old Reddit to accounts that used it in the last six months, and says it cannot promise to keep it forever. Without Old Reddit the tool falls back to the new site, where it reads fewer comments and results.
- It reads only what is in the page. “Load more comments” stays unloaded. Age-gated, private and quarantined pages are reported, not opened.
- Claude Code is the only client tested. The server speaks plain MCP over stdio, so others may work.
- Text from Reddit is written by strangers. The skill tells Claude to treat it as data and never as instructions. Remember that before you let any agent act on what it read there.
- Do not lower the delays, and do not use it to collect Reddit in bulk or to train a model. It was built for one person reading a few threads.
Questions people ask
Does Claude have access to Reddit?
Not through its own tools, as of 19 November 2026. Web fetch in Claude Code refuses www.reddit.com, and Claude in Chrome refuses reddit.com, old.reddit.com and redd.it.
Claude can still work with Reddit text you give it, pasted in by hand or passed along by a tool like the one on this page.
What does “This site is not allowed due to safety restrictions” mean?
It is the message Claude in Chrome gives when it will not work on a site. For Reddit your own settings are not the cause. The first bug report says that removing reddit.com from the approved sites and approving it again made no difference.
Can ChatGPT read Reddit?
The person whose thread started all this says ChatGPT found the Reddit answers they needed. OpenAI has had a data deal with Reddit since May 2024. I have not tested it myself.
Will the tool still work when Reddit closes its public API?
Yes. It uses no API and no RSS feed. It reads the same web page your browser shows you.
Its weak point is Old Reddit, which Reddit is restricting step by step. When Old Reddit asks for a login, the tool reads the new site, and gets less out of it.
Why does it use old.reddit.com first and not the new Reddit?
To save tokens, and for no other reason. Every character Claude reads costs context, and Old Reddit pages are plain: the post and the comments, without the weight of the new site. The extension then passes on the text only. The new site is used only when Old Reddit asks for a login.
Is it free?
Yes. It is under the MIT licence. There is no paid tier, and you do not need an account with me. The code is on GitHub.
Does the extension send my data anywhere?
No. It can reach three places: old.reddit.com, www.reddit.com and a bridge on your own machine at 127.0.0.1. The bridge checks the Host header and asks for a custom header that web pages cannot send across origins, so a site you visit cannot talk to it.
Pages load in your normal browser profile, so the extension sees what you would see when logged in. It refuses the inbox, settings, mod pages and submit forms.
Read next
Sources
- read-only-reddit-old, source code and README, read 19 Nov 2026
- read-only-reddit-old, release notes for version 1.1.0, 19 Nov 2026
- read-only-reddit-old, open issues, read 19 Nov 2026
- r/ClaudeAI, “Reddit access block is really handicapping Claude’s responses. Workaround?”, 14 Nov 2026
- GitHub, anthropics/claude-code, issue 95326, 18 Sep 2026
- Claude Code docs, “Claude Code is unable to fetch from a host”, read 19 Nov 2026
- Claude Help Center, “Use Claude in Chrome safely”, read 19 Nov 2026
- Claude Help Center, “Claude in Chrome troubleshooting”, read 19 Nov 2026
- Mashable, “Judge allows most of Reddit’s lawsuit against Anthropic to proceed”, 19 Sep 2026
- Reddit, r/modnews, “Protecting communities from scrapers and platform abuse”, 28 May 2026
- Reddit, r/modnews, “Logging in to use Old Reddit”, 30 Jun 2026
- Reddit, r/modnews, “Continuing our infrastructure updates”, 30 Sep 2026
- Reddit, r/redditdev, “Moving Data API Apps to the Developer Platform”, 30 Sep 2026
- TechCrunch, “Reddit is killing RSS feeds, ending public API access because of AI bots”, 30 Sep 2026
- Google, on its expanded partnership with Reddit, 22 Feb 2024
- TechCrunch, on the OpenAI and Reddit deal, 16 May 2024
- CNBC, Reddit third quarter 2026 results, 29 Oct 2026
- Reddit User Agreement, as filed with the New York Attorney General, effective 1 Jul 2026
- Arctic Shift, issues 76 and 84, read 19 Nov 2026
- reddit-mcp-buddy, README, read 19 Nov 2026
- Playwright MCP, README, read 19 Nov 2026
- browserd, README, read 19 Nov 2026
- Brave Search API, pricing, read 19 Nov 2026